Søndagens læsning

Dagens Vibes — 13. september 2026

Agentkvalitet er ved at blive et målesystem i stedet for promptmagi. Samtidig er lokale open weights begyndt at ligne værktøj — ikke bare et dyrt varmeapparat med tokens.

Fra X-feedet

Astra-regressionen havde tre meget jordiske årsager

Efter ugens ujævne vibe checks kommer postmortemet: overaktive gamle skills, et konteksteksperiment der ramte 4–5.000 brugere og fejlkonfigurerede engines. OpenAI anbefaler samtidig kortere skill-triggere, progressive disclosure og en eksplicit definition af “færdig”. Promptarkæologi er blevet drift.

Tibo@thsottiaux
Hi Astra users. A reset and a quick update on quality issues that have been posted around. Working with some of you, we have found and fixed the following issues: - Some skills written for previous models were triggering too often or preventing the model from checking its work. - An opt-in context management experiment that could cause early stops or replies to older messages. We've disabled it. Our rough estimate is that 4-5k users were affected by this experiment. - We've also removed some badly configured engines that resulted in a measured quality degradation for a long tail of traffic flowing through them. We’ve also made some more minor improvements and things should feel significantly better across the board. More consistent follow-through, better tracking of your latest message, and better checks on the work as it’s going through the motions. The examples posted and all the users who worked directly with us were incredibly useful in helping fix things quickly. Always grateful for this incredible community. And of course, a reset is also landing by midnight today.
♥ 27.570   ↻ 1.578   💬 3.873   🔖 2.525
https://x.com/thsottiaux/status/2098612714704891959

Reset-bekræftelsen · OpenAI: skills og prompts til Astra

Skills får endelig en kontrolgruppe

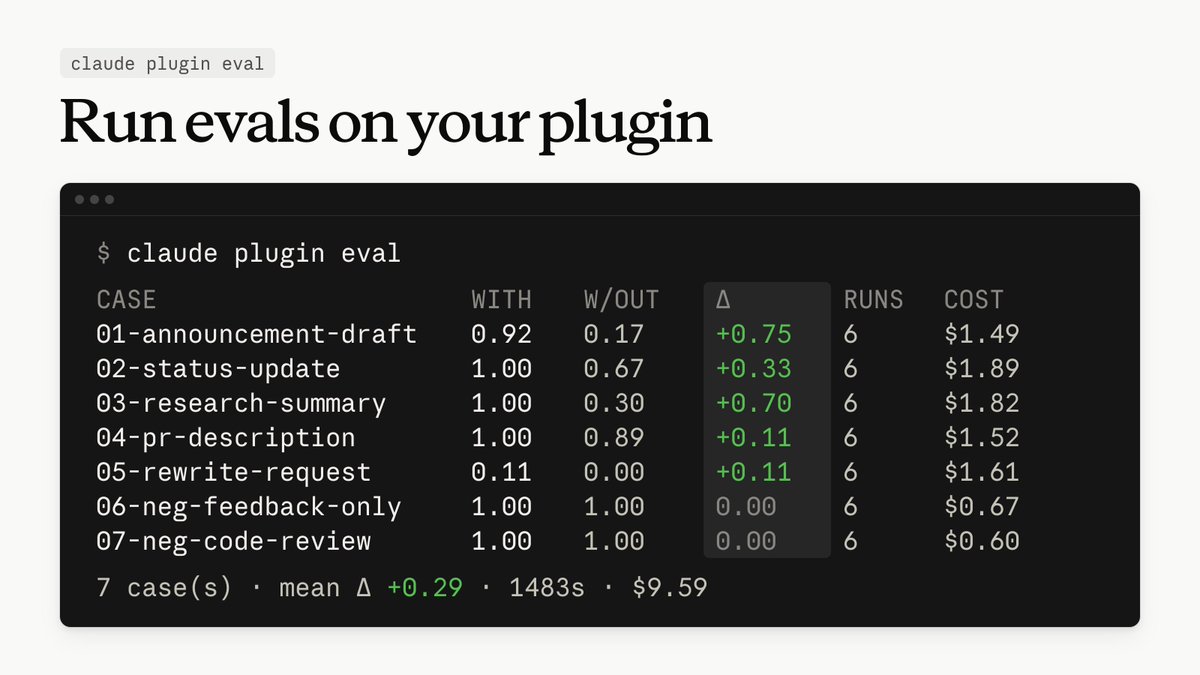
claude plugin eval kører de samme cases med og uden en plugin eller skill og laver en scoret rapport. Addy Osmanis parallelle pointe er lige så brugbar: skriv outcome, blast radius og de præcise checks ind — og gør hver review-fejl til genbrugelig instruktion. Det er CI for agentadfærd.

ClaudeDevs@ClaudeDevs
New in Claude Code: claude plugin eval See what value your plugin is adding, or if it needs more work. You can create test cases, run your plugin or skill against those test cases, score those runs, then run each case again without the plugin to see the differences. https://t.co/qfPU6WHueV
Claude plugin eval rapport
♥ 5.733   ↻ 394   💬 169   🔖 4.484
https://x.com/ClaudeDevs/status/2098500999656923145
Addy Osmani@addyosmani
How do you hold the bar on production agent code?: 1. Agree on the outcome and the constraints first. What does "done" look like? what must it not touch? is the simpler design is to refactor or reuse what you already have? Then let Claude cook. You do not need a long planning ritual on the latest models. You do need to reject a bad change before it becomes a PR. 2. Give Claude a way to check its work. Put the exact build, test, and lint commands in there. Turn the things you reject in review into skills: /verify, e2e, schema checks and so on. Run those before you open the PR. Use /code-review. I've said that quality now lives in the constraints you put around your agents and think this is worth spending time on. 3. Your job is the design and the bar. Blast radius decides how much you read. Throwaway code with a small blast radius can be a black box. Production code should have a higher bar than if a human wrote it, especially anything that touches money, auth, or user data. 4. When Claude misses, don’t quietly fix it by hand. Have it write the lesson into CLAUDE.md or a skill. If it still misses, use the latest frontier model, turn effort to higher or have Claude pay down the debt and make the codebase easier to work in. You can start with one check you already run today on every PR. The rest compounds from there.
♥ 279   ↻ 18   💬 49   🔖 325
https://x.com/addyosmani/status/2098662421644853433

Claude Code 2.1.269 release notes

Én DGX Spark, fire seriøse modeller

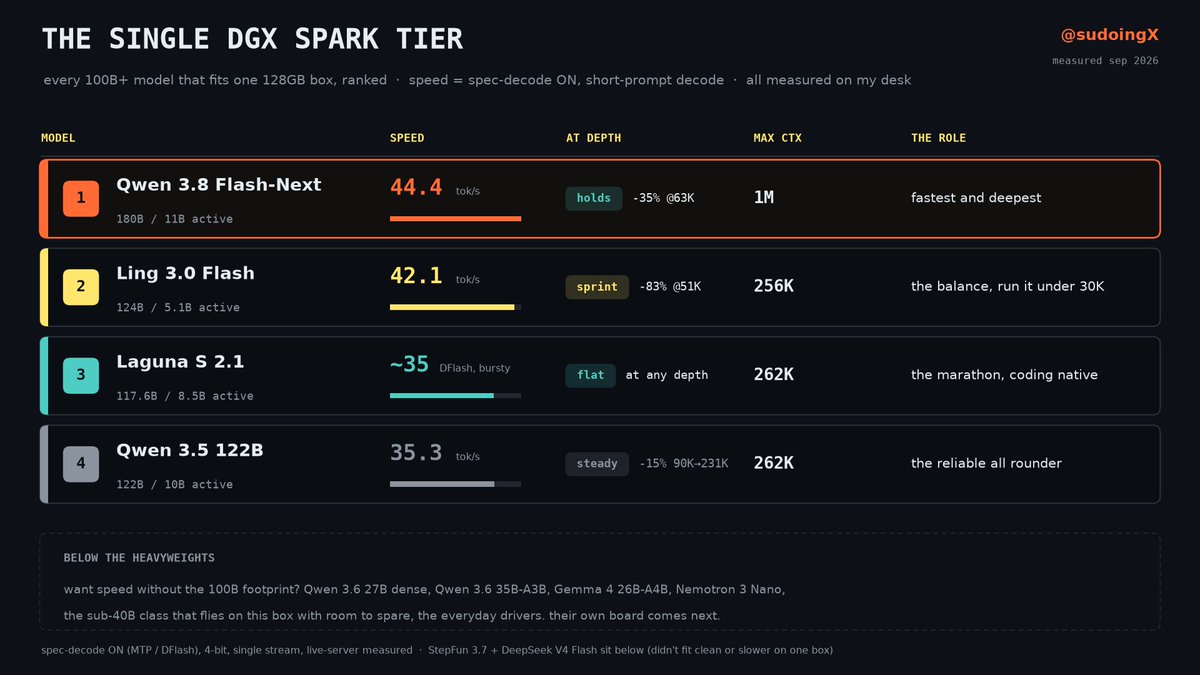
To ugers skrivebordstest er mere værd end endnu en leaderboard-sejr: Qwen 3.8 Flash Next vandt den samlede fart-rangering; Ling 3.0 Flash fulgte tæt, men faldt 83 procent ved 51K. Ling byggede til gengæld tre rigtige projekter, bestod 18/18 tests og genoptog arbejdet efter gentagne crashes. Det er et ordentligt vibe check — med både kvitteringer og blå mærker.

Sudo su@sudoingX
i spent two weeks living on every 100B+ model that fits one dgx spark 128gb and this is the list i wish existed the day the box landed. every option i could find, tested on this box, what survived is ranked below, all measured on my desk: > 1. qwen 3.8 flash next, 180B with 11B active, 44.4 tok/s, holds its speed at depth (-35% at 63K), 1M context fits in memory (measured to 128K) @Alibaba_Qwen official: https://t.co/Ie4IU9vveJ > 2. ling 3.0 flash, 124B with 5.1B active, 42.1 tok/s on the official int4, mit license, the fastest vendor-official release on the board, opens level with flash-next and collapses as the context fills (-83% at 51K), 256K context @AntLingAGI official int4: https://t.co/3oXqG8LUwZ > 3. laguna s 2.1, 117.6B with 8.5B active, ~35 tok/s on code with dflash, flat at any depth, 262K context, coding native @poolsideai official: https://t.co/PrQdrNchsT > 4. qwen 3.5 122B, 122B with 10B active, 35.3 tok/s with mtp, -15% from 90K to 231K, 262K context, the reliable all rounder @Alibaba_Qwen via @UnslothAI's nvfp4: https://t.co/gKkCfH5lUt the cuts matter as much as the picks. deepseek v4 flash fits at 3bit and decodes 16.5 tok/s with no drafter on one box, too slow to build with. stepfun 3.7 flash nvfp4 is 121GB, zero headroom, it took the box down twice before it ever served a token. a few more went the same way. the one i ran hardest sits at #2. most of these two weeks i lived on ling and co-built three agentic builds on camera, i know that model better than anything else on this box, and it still lands second on speed. that is the point of measuring. the receipts are in the replies, and from here the box belongs to flash-next and other new models, same treatment, numbers will land. this board is speed, depth and context, the three numbers you feel every day on one dgx spark.
Sammenligning af lokale modeller på DGX Spark
♥ 123   ↻ 14   💬 33   🔖 119
https://x.com/sudoingX/status/2098681025950048692
Sudo su@sudoingX
i pointed hermes agent at ling on one spark and let it build three real things. a full game, 2,366 lines, 18 of 18 tests green: https://t.co/hxXQ02DE0h the most useful tool in my agentic stack, nopasswd-sudo, now open source and running on every machine i own: https://t.co/nmdQo9y2Ft and yesterday a working expense tracker, the box crashed at the finish line and the model resumed its own plan and shipped: https://t.co/Tjr9oBxIHd
Ling 3.0 Flash bygger et spil lokalt
♥ 4   ↻ 0   💬 1   🔖 3
https://x.com/sudoingX/status/2098681032904253449

Opskriften til Ling på DGX Spark · Qwen 3.8 Flash Next

Et lille sprog til den sidste kilometer mod Markdown

Knap tager JSON, CSV eller HTML og former det til Markdown fra CLI eller som bibliotek. Det begyndte inde i Obsidian Web Clipper og er blevet skilt ud som open source — meget niche, meget brugbart og udtalt med hårdt k. Naturligvis.

kepano@kepano
This is Knap. It's a new language I created that turns data into Markdown. The syntax should feel familiar and comes with wonderfully pleasant features to modify and format plain text. Knap is open source. Over a million people already use Knap directly or indirectly because it started as the templating language I made for Obsidian Web Clipper. Now any tool can use it. You can add Knap to your app or use it via CLI. Create a batch of Markdown files from JSON or CSV, or pipe Defuddle directly into Knap to generate Markdown from HTML/URLs. The Knap site is color-coded to help beginners understand the relationship between variables (blue), filters (orange), and logic (green). I've tried to document it as comprehensively as I can. Try the Knap Playground so you can see how fun the syntax is to use! Knap is pronounced /knæp/ (with a hard k). It's named after knapping (with a silent k): the process of shaping stones to form arrowheads, scrapers, and other tools. Enjoy!
Knap omsætter data til Markdown
♥ 4.032   ↻ 264   💬 83   🔖 2.755
https://x.com/kepano/status/2098126579826377066

Fundet via Steve Ruiz

Nyhedsbonus

Dario Amodei vil sænke farten på frontier-modeller og starter med det mindst glamourøse, mest konkrete greb: eksterne evaluatorer med badge, laptop og næsten samme adgang som interne risikoteams. Sam Altman siger, at OpenAI følger trop; næste trin kræver brancheaftaler og til sidst koordinering med Kina. Labsene har opdaget, at “trust us” ikke er en eval.

TechCrunch · 12. september

Anthropic foreslår at “pace the frontier”

En plan i tre trin: indlejrede kontrollanter, fælles standarder og global koordinering.

Læs Amodeis fulde forslag

Real-SWE tester otte model/harness-kombinationer på ti opgaver fra private produktionskodebaser med moms, billing, migreringer og integrationsrod. Fable 5.1 topper på 38,8 procent løste runs, Astra lander på 33,8 og seks af ti opgaver har under 15 procents succesrate. Den ægte virksomhedskode er fortsat chefkampen.

Specific Labs · 12. september

Ny benchmark bruger private enterprise-kodebaser

Ingen model når 40 procent; oversete krav er den hyppigste fejl.