Tirsdagens briefing

Dagens Vibes — 6. oktober 2026

Modellerne får nye motorer. Agenterne får hukommelse og tilstand — og en slikautomat reparerer sig selv.

Fra X-feedet

Beam: en vestlig open-weight-kandidat

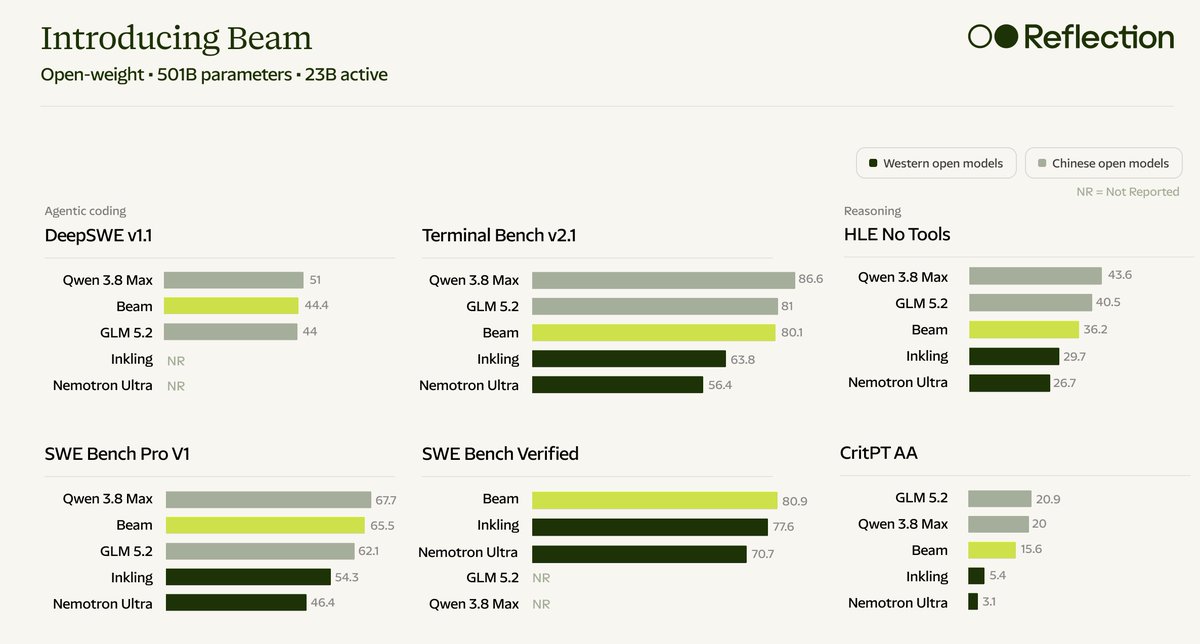
Reflection annoncerer 501 mia. parametre, 23 mia. aktive og vægte senere i oktober. Interessant for intern AI — men endnu en kandidat, ikke et dokumenteret alternativ til vores hovedmodel.

Reflection@reflection_ai
Introducing Beam: a highly efficient agentic open model with 501B total parameters and 23B active. - Frontier reasoning efficiency - Advances the Western open frontier on coding & agentic tasks - Trained end-to-end from scratch Full weights release this month. Learn more about Beam: https://t.co/c3Qx2cpM8G
Medie fra opslaget
♥ 5.333 · ↻ 718 · 💬 331 · 🔖 2.161
https://x.com/reflection_ai/status/2107186849370247235
Læs lanceringen · vægtene er ikke frigivet endnu

Træn i det værktøj, modellen faktisk skal bruge

Samme model scorede 62 % i ét harness og 33 % i et andet. Hugging Face træner gennem rigtige coding-harnesses, inklusive Pi; i et lille forsøg forbedredes LFM2.5-2.6B på tværs af fire og brugte færre tool calls.

clem 🤗@ClementDelangue
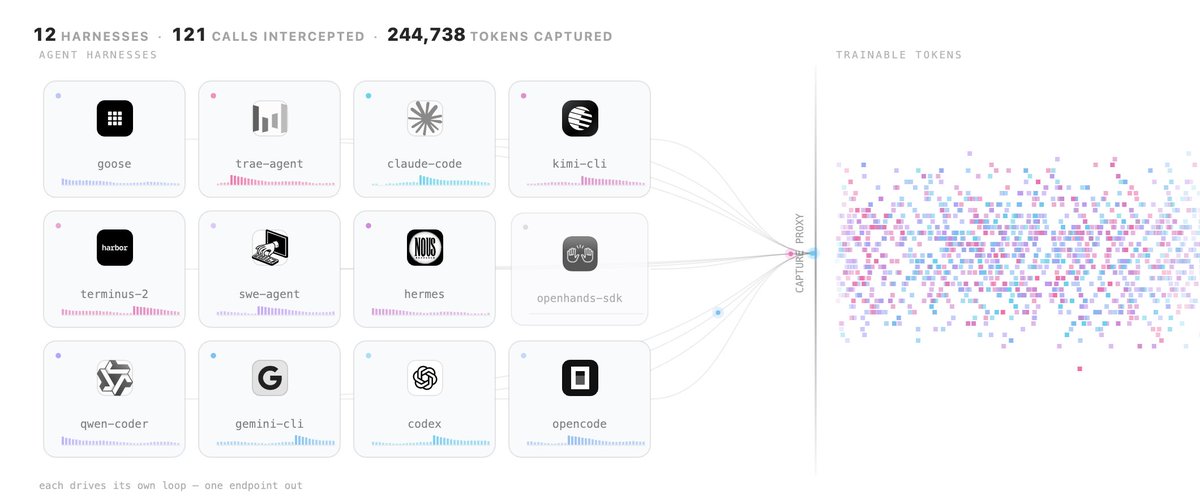
We turned Claude Code, Codex, Hermes, Pi, @opencode and other coding harnesses into RL environments. No changes to the harnesses, no changes to the training code. Any open model, any task set, fully open source my friends! Same model, same weights: 62% under Mini-SWE-Agent, 33% under Claude Code. But training inside a real harness normally means reimplementing it as an environment, so most models get trained in a scaffold nobody actually ships. The fix is a proxy, not a rewrite. The harness thinks it's talking to a model API. It's actually talking to a capture proxy that speaks the 4 formats coding agents use (OpenAI Chat Completions, OpenAI Responses, Anthropic Messages, Gemini), forwards to @vllm_project, records the exact token IDs and logprobs vLLM sampled, and hands TRL sequences it can train on. The harness becomes the environment. 10 harnesses run through it today, none modified. And because you control the reward, you can shape behavior the harness never asked for. We added a small bonus for solving a task in fewer tool calls: on tasks it already solved, the model now uses 31% fewer calls, in every harness, and about half under Codex. Tested on LFM2.5-2.6B from @liquidai: → Train in one harness: better mostly in that harness (OpenCode 34% → 58%). → Train in 4 at once: better in all 4 (42% → 54%). → SFT on 3,189 rollouts from Qwen3.8-27B instead: plateaus at 47.5%, below both RL runs. Everything is open and reproducible: the capture proxy in OpenEnv, the trainer in TRL, the tasks, the SFT data, the training code and all 7 trained models. Bigger models and bigger runs next. Full guide: https://t.co/sKZURuOcza
Medie fra opslaget
♥ 1.798 · ↻ 219 · 💬 162 · 🔖 1.567
https://x.com/ClementDelangue/status/2107120717980471638
Åben guide til multi-harness RL

En agent er ikke bare sin chathistorik

Mario rammer den afgørende Durable-pointe: værktøjer undervejs, subagents og applikationstilstand skal også overleve. At huske samtalen og at genoptage arbejdet er to forskellige problemer.

Mario Zechner@badlogicgames
an agent is more than its transcript. an agent has inflight tools, application state it needs to i/o, subagents etc. pi durable is exactly that state first solution, covering more than just the transcript. and we recommend people use effect in the application layer on top of pi durable.
♥ 6 · ↻ 0 · 💬 3 · 🔖 2
https://x.com/badlogicgames/status/2107081805358576023

Hukommelse som Git-repo

Cognition vælger Markdown, links og Git-historik frem for et komprimeret samtaletræ. En interessant kontrast til OptChat: eksplicit viden, som kan versioneres og deles mellem agenter.

Walden@walden_yan
We're also open-sourcing our memory format: - support graph relationships - updates over time with historical records - backed by git and markdown and you can use it with any agent, not just Devin!
♥ 1.420 · ↻ 63 · 💬 50 · 🔖 1.804
https://x.com/walden_yan/status/2107185315014144357
Agent Memory Repo · åben specifikation

Qwen 3.8 27B: reasoning gør en reel forskel

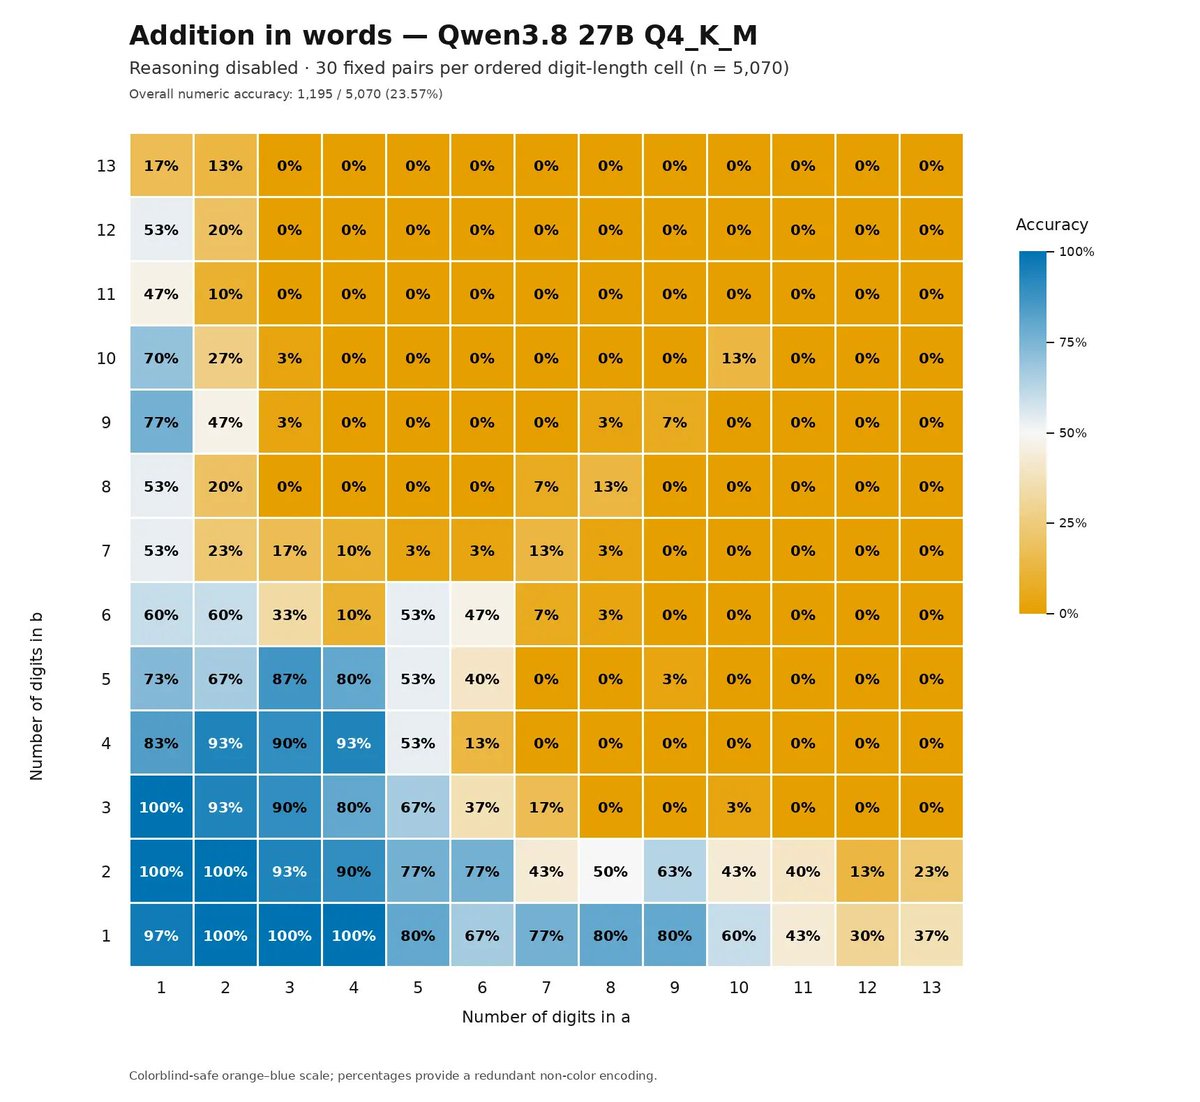
Willisons lokale regneforsøg gav 23,57 % korrekte svar uden reasoning; med medium reasoning blev det 167 af 169 i et mindre pilotforsøg. Ikke en projektledertest, men en god påmindelse om at afprøve den konkrete modelkonfiguration.

Simon Willison@simonw
I re-ran an experiment @colin_fraser ran against GPT-4o a while back to see how good it was at adding long numbers, only this time I tried Qwen 3.8 27B running locally in both reasoning and non-reasoning modes https://t.co/IOufJIA4N9 https://t.co/4kB33NCPcO
Heatmap in the same layout as the previous chart, using an orange (low) to white to blue (high) color scale, showing much lower accuracy overall. Title: Addition in words — Qwen3.8 27B Q4_K_M. Subtitle: Reasoning disabled · 30 fixed pairs per ordered digit-length cell (n = 5,070). Overall numeric accuracy: 1,195 / 5,070 (23.57%). X axis: Number of digits in a, 1 to 13. Y axis: Number of digits in b, 1 to 13. Legend: Accuracy, 100%, 75%, 50%, 25%, 0%. Values by row, listed for a = 1 to 13. b = 13: 17%, 13%, 0%, 0%, 0%, 0%, 0%, 0%, 0%, 0%, 0%, 0%, 0%. b = 12: 53%, 20%, 0%, 0%, 0%, 0%, 0%, 0%, 0%, 0%, 0%, 0%, 0%. b = 11: 47%, 10%, 0%, 0%, 0%, 0%, 0%, 0%, 0%, 0%, 0%, 0%, 0%. b = 10: 70%, 27%, 3%, 0%, 0%, 0%, 0%, 0%, 0%, 13%, 0%, 0%, 0%. b = 9: 77%, 47%, 3%, 0%, 0%, 0%, 0%, 3%, 7%, 0%, 0%, 0%, 0%. b = 8: 53%, 20%, 0%, 0%, 0%, 0%, 7%, 13%, 0%, 0%, 0%, 0%, 0%. b = 7: 53%, 23%, 17%, 10%, 3%, 3%, 13%, 3%, 0%, 0%, 0%, 0%, 0%. b = 6: 60%, 60%, 33%, 10%, 53%, 47%, 7%, 3%, 0%, 0%, 0%, 0%, 0%
♥ 337 · ↻ 17 · 💬 71 · 🔖 108
https://x.com/simonw/status/2107158711798218848
Læs forsøget · inklusive kode og reasoning-sammenligning

Smalltalk får en lille mekaniker indbygget

Recast lader en fejl udløse et LLM-fix, tester det i en separat VM og udskifter metoden i den kørende app. Demoen er en slikautomat — ikke selvhelende enterprise — men hot reload har fået en ret sjov kollega.

rijndael@rot13maxi
inspired by @GeoffreyHuntley smashing lisp and llms together, I wired an LLM into a Smalltalk app’s exception path: a failing call triggers a proposed repair, tests it in a separate VM, and patches the running app. No restart. https://t.co/2ut8eAUqPm
♥ 69 · ↻ 11 · 💬 7 · 🔖 42
https://x.com/rot13maxi/status/2107126295544885289
Recast · kode og reproducerbar demo

Nyhedsbonus

Jobsamtalen tester også din brug af AI

HackerRank gjorde mandag Chakra generelt tilgængelig: en AI-interviewer, der ser kandidaten arbejde i et rigtigt repo med en AI-assistent og spørger ind til valgene. Mere relevant end endnu en algoritmeøvelse uden værktøjer — hvis den faktisk kan bedømme dømmekraften.

TechCrunch · 5. oktober 2026
HackerRanks AI-interviewer bliver generelt tilgængelig