Torsdagens briefing

Dagens Vibes — 8. oktober 2026

Chatten bliver interaktiv, småmodeller bliver brugbare, og agentfabrikken skal kunne efterprøves — og betale sin egen VVS-regning.

Fra X-feedet

Chatten får en grænseflade til opgaven

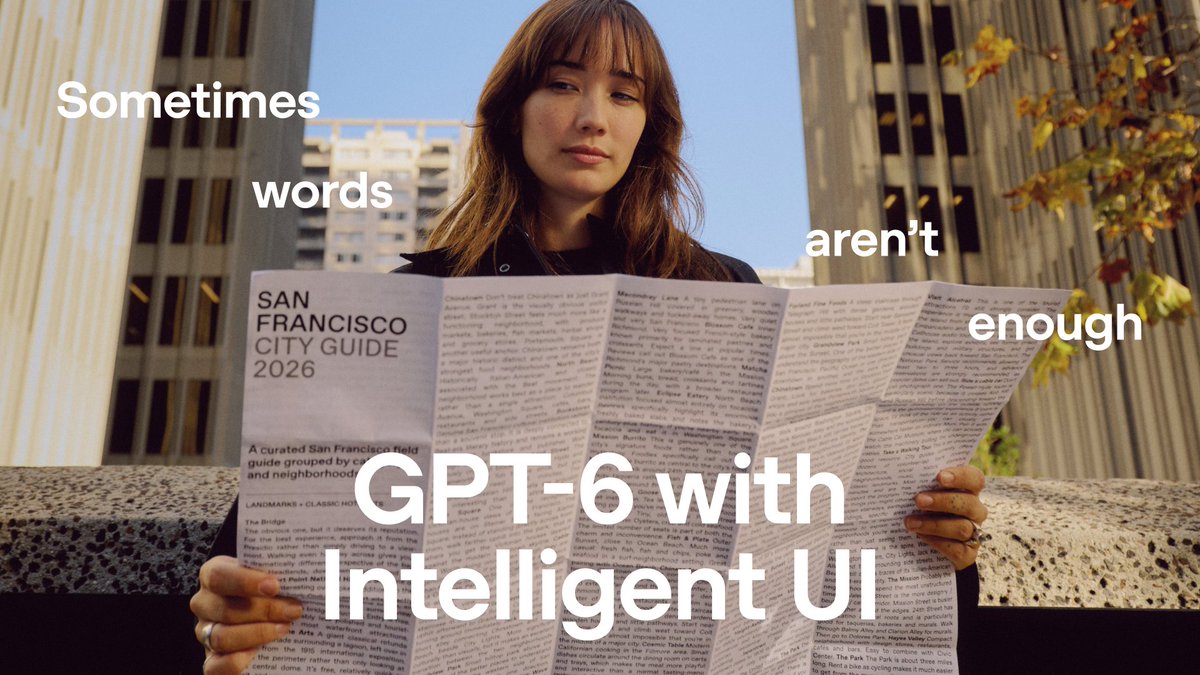
GPT-6 kommer i ChatGPT med interaktive diagrammer, formularer og små værktøjer direkte i svaret. Mollick har prøvet det: mindre tekstmur, mere interface efter behov — et større skifte end endnu en model i dropdownen.

Ethan Mollick@emollick
Had early access to the Intelligent UI experience and it was a nice change from walls of text. It also suggests that, increasingly, we are going to see interfaces built on demand for the problem that you have.
OpenAI@OpenAI
GPT-6 and Intelligent UI, now rolling out in ChatGPT for everyone. Intelligent UI in ChatGPT delivers fast, interactive answers that make everyday questions more visual, complex topics easier to grasp, and interactive tools for your task available on the spot. https://t.co/XL2gDCPBwG
Medie fra opslaget
♥ 380 · ↻ 17 · 💬 47 · 🔖 63
https://x.com/emollick/status/2107938889004396561
OpenAI · Intelligent UI, udrulning og hvilke modeller der bruges

Haiku 5.5: billig arbejdshest, med en priskant

Haiku rammer Lunas $0,10/$0,50 pr. million input/output-tokens under 100k kontekst; over grænsen bliver begge priser femdoblet. Willisons egne forsøg viser også cirka 25 % flere tokens for samme lange prompt — billig pr. token er ikke hele regnestykket.

Anthropic · lancering, effort og prisniveauerWillisons hands-on · pelikaner, tokenizer og API-kreditter

Vibe check: browser-QA til småmodelpris

Kevin Kern kørte Opus 5 og Haiku 5.5 på browserbrug: Haiku overså én defekt, men virkede prismæssigt som en mulig erstatning. Et lille, konkret forsøg — ikke bevis for at fyre alle de store modeller.

Kevin Kern@kevinkern
did a quick test for browser use. opus 5 vs haiku 5.5. haiku missed one defect, but price-wise, it looks like a good drop in replacement. https://t.co/zKMc6hYTU1
Medie fra opslaget
Kevin Kern@kevinkern
really interested in haiku 5.5 for computer/browser use. spawn a ton of cheap & fast agents to run live tests on your apps.
♥ 8 · ↻ 0 · 💬 0 · 🔖 0
https://x.com/kevinkern/status/2107937906027348016

Kan agenten bevise, at din kode stadig virker?

Laurens “time to rewrite” er et tankeeksperiment, ikke en ny KPI: Hvis du ikke ville stole på en automatisk omskrivning, hvilke verifikationsmuligheder mangler så allerede i dit daglige flow? Bedre spørgsmål end hvor mange agenter man kan stable.

lauren@poteto
something I have been thinking about is a way to approximate how well you’ve setup your codebase for agents. think of it as a thought experiment and rough heuristic, not a real number that can be compared it’s not a fully formed idea yet, but i think there’s something to the idea of “time to (fully automated, hands off) rewrite” or ttr as a thought experiment, lets say you decided to rewrite your code in a different language/framework/architecture. how long would it take a single engineer to do it? the number itself isn’t that important, but it leads you to more questions that can help you directionally figure out how to make your codebase more legible and productive for agents. for example, maybe you think your ttr is high because you wouldn’t trust the final result - because your agents don’t have a way to verify their work and convince you that their output is identical in user visible behavior to the original. well, that inability is likely also a problem today and slows you and your agents down there’s also a more subtle question of the quality of the rewrite that would be produced. is perf better, the same, or regressed? is the code easy to delete and extend? and how much do you trust the rewritten version to be able to maintain its quality over time as PRs start flowing into it? what do you think?
♥ 1.207 · ↻ 33 · 💬 136 · 🔖 628
https://x.com/poteto/status/2107913381751730352

Det usexede arbejde sparer de rigtige penge

Theo beskriver cirka 30 iterationer af T3 Codes PR-overvågning og over 75 % lavere forbrug af GitHubs rate limits. Det er API-budget, ikke en målt tokenbesparelse — men pointen rammer: agentfabrikkens VVS betyder noget.

Theo - t3.gg@theo
I really hope everyone copies the work we did here. I’ve been thinking about how many tokens are wasted with bad PR monitoring flows and it made me feel a bit sick
Theo - t3.gg@theo
I have spent far too much time on the Github integrations in T3 Code the last few days. Cut rate limit usage by over 75% and made monitoring behaviors much more reliable. Julius moved us off the CLI for API calls we can do more efficiently directly. We rotate between the GQL and rest APIs depending on which uses your rate limits most efficiently (with fallbacks). This was a ton of work that will largely go unnoticed, but it's the type of stuff I love. Had to do like 30 implementations of the PR watcher before I got it to a good spot. On one hand, I'm thankful the details can be seen by those who dig into the source code. On the other, feels weird that everyone else will just copy our work and never have to think so much about this.
♥ 653 · ↻ 10 · 💬 36 · 🔖 176
https://x.com/theo/status/2107913767380267408

Fire lokale agenter på ét 16 GB-kort

Sudo su viser fire Hermes-agenter bygge spil på en RTX 5060 Ti med en komprimeret Qwen 3.8 27B. Ved cirka 60k kontekst pr. agent rapporterer han 10–11 tokens/sekund hver; interessant hjemmehardware, ikke bare et kort prompt-demo-tal.

Sudo su@sudoingX
4 agents running concurrently on a single 5060 ti, watch them build 4 games anon. what one 16gb card pushes: > 124.7 tok/s, 4 short chats running at once > 42 tok/s, 4 agents each holding ~60k of context > 10 to 11 tok/s per agent at that depth bonsai 2 is qwen 3.8 27b squeezed to 5.95gb, so here's what it does on the cards might own: > 12gb like a 3060, one agent at about 50 tok/s > 16gb like a 5060 ti, one agent at about 67 tok/s > the full 262k window with vision still fits in 16gb each agent got one paragraph of plain english and an empty folder, hermes agent drove all four at once, no cloud, and the whole thing used over 90% of the card's 16gb drop your gpu below and i'll tell you which row you're in
Medie fra opslaget
Sudo su@sudoingX
your rtx 5060 ti 16gb can run 4 autonomous coding agents at once > 76 tok/s total, 17 to 21 tok/s each > 4 hermes agents, building 4 games in parallel > 64k context per agent > 67 tok/s single stream with mtp > 15.6 of 16 gb vram, 130 w > bonsai 2 27b ternary, 5.95 gb > one llama.cpp server, 4 slots each got one prompt with words only, and the video is 42 minutes of all four thinking and writing at once, sped up to 3 minutes
Medie fra opslaget
♥ 40 · ↻ 2 · 💬 7 · 🔖 19
https://x.com/sudoingX/status/2107819104724025425

Margaret Hamilton, 1936–2026

MIT offentliggjorde i går mindeord om Apollo-softwarepioneren, der døde 30. september. Midt i al agentsnakken er historien om prioritering, fejl og rigtig software engineering stadig værd at læse.

Jeff Dean@JeffDean
Very sorry to hear this news. 😥 I never had the chance to meet Margaret Hamilton, but her contributions to the flight software that got us to the moon are legendary. I love this image of her standing next to the printouts of the Apollo code. https://t.co/2HJPXcTfiC
Medie fra opslaget
Massachusetts Institute of Technology (MIT)@MIT
We’ve lost an icon. Margaret Hamilton, a computer science pioneer best known for her work at MIT leading development of the flight software for the Apollo missions to the moon, has died at 90. Read about her legacy via MIT News: https://news.mit.edu/2026/margaret-hamilton-computing-pioneer-dies-1007 https://t.co/M2xauYYUkU
Margaret Hamilton is reclined inside a NASA spacecraft module, surrounded by control panels and switches.
♥ 329 · ↻ 32 · 💬 4 · 🔖 19
https://x.com/JeffDean/status/2108027570382086435
MIT · Hamiltons arbejde og arv

Nyhedsbonus

Surface bliver en lokal AI-boks

Microsoft åbnede 7. oktober forudbestillinger på Surface RTX Spark Dev Box: 128 GB samlet hukommelse, $5.999 og levering fra november, foreløbig kun i USA. Lokal modeldrift får færdig hardware — og en pris, der ikke gemmer sig i tokenregningen.

Unite.AI · pris, hardware og udviklermiljø