Mandagens briefing

Dagens Vibes — 12. oktober 2026

Bedre agentarbejde gennem faglighed, holdbar eksekvering og tests på den rigtige hardware.

Fra X-feedet

Ekspertise giver bedre agenter

Sean Goedecke bruger Terence Taos ChatGPT-samtale til at vise, hvorfor faglig dømmekraft gør samme model langt mere nyttig. At kunne sige “det kan gøres enklere” er stadig en superkraft.

Sean Goedecke · LLMs reward expertiseFra feedet · faglighed, steering og konkrete spørgsmål

Unikernels får en ny chance

Geoffrey Huntley og Justin Cormack genbesøger idéen om en app, der selv er operativsystemet. Det stærkeste eksempel: en agentbygget mkfs.xfs i Rust, verificeret mod originalens output.

geoff@GeoffreyHuntley
🗞️ unikernels were hard. key word: were. http://ghuntley.com/unikernels Justin Cormack, who worked on MirageOS back in the day, called me at the pub to talk about why unikernels are coming back. The friction that made them hard is gone; the operating system is design debt, and if you care about security, you should seriously consider them.
Billede fra opslaget
♥ 324 · ↻ 49 · 💬 21 · 🔖 248
https://x.com/GeoffreyHuntley/status/2108926918540378117

Delt igen i døgnets feed af Anil Madhavapeddy.

Unikernels were hard. Key word: were.Portering, test-orakler og mindre systemer

Durable codemode

Mario Zechner viser interne, dynamiske workflows med durable eksekvering og subagents, man kan inspicere og styre. Det rammer ret direkte ned i Battys maskinrum.

Mario Zechner@badlogicgames
also cool: things like claude code's dynamic workflows fall out for free, durably :D and i can even inspect everything subagents of such a workflow do (or steer them if absolutely needed)
Video-preview
♥ 154 · ↻ 3 · 💬 18 · 🔖 81
https://x.com/badlogicgames/status/2109413968552820840

Bonsai 2 på en gammel gaming-GPU

Sudo deler Matt Wolfgangs test: Bonsai 2 27B mod Qwen 3.6 på en Python-todoapp med tests, kørt på en RTX 2080. Ifølge forsøget skrev Bonsai bedre kode med høj reasoning; repoet gør lokal afprøvning konkret.

Sudo su@sudoingX
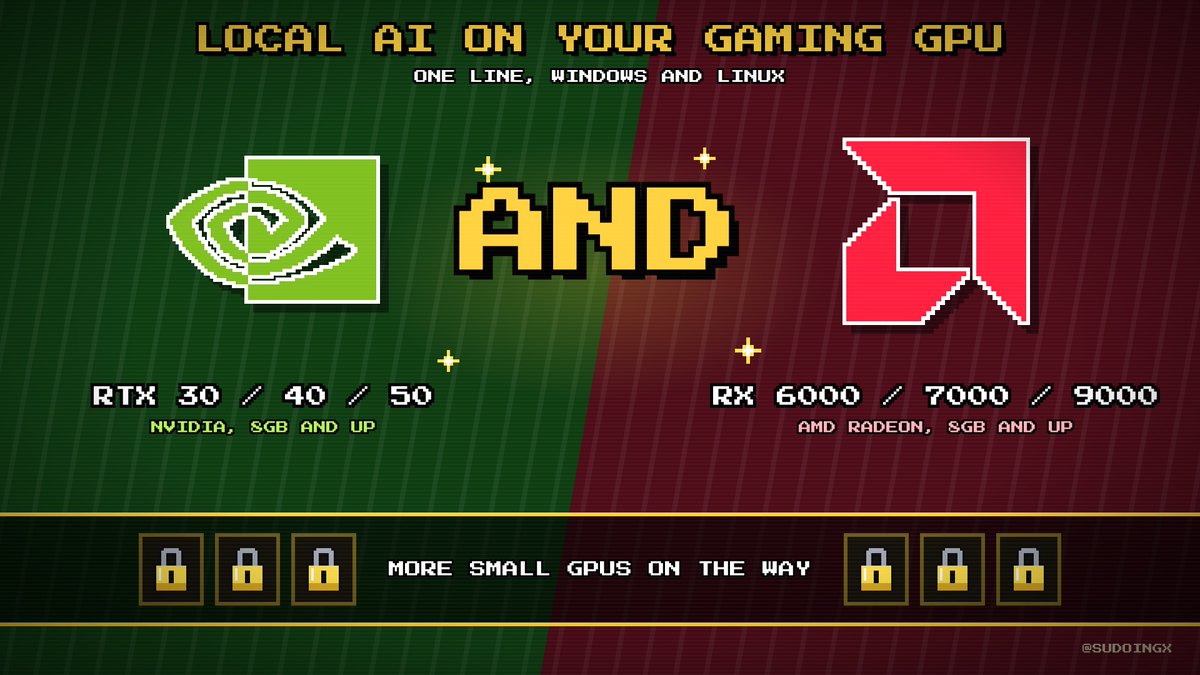
anon look, this is what adopting local ai looks like, matt took an rtx 2080, a 2018 card with 8gb vram, and ran bonsai 2 27b against qwen 3.6 35b-a3b on a python cli todo app with tests, and on high reasoning the 27b wrote the better code here's how to run your own, rtx 30, 40, 50 or a radeon with 8gb and up, on windows or linux > windows, paste in powershell: irm https://raw.githubusercontent.com/sudoingX/local-ai-on-your-gaming-gpu/main/install.ps1 | iex > linux, paste in terminal: curl -fsSL https://raw.githubusercontent.com/sudoingX/local-ai-on-your-gaming-gpu/main/install.sh | bash what your card gets from the one line > rtx 8gb, 98K context, 64K if it also drives your display > rtx 12gb, 131K with the speed head > rtx 16gb and up, the full 262K > radeon 8gb up to 64K, 12gb about 195K, 16gb 262K with vision post your results even when they're ugly, a failed run tells the next person with your card what to change. if you ran it on a card nobody has tried yet, post that too, someone with the same card is waiting for exactly that thank you matt, this is why i packaged it
Billede fra opslaget
♥ 53 · ↻ 4 · 💬 7 · 🔖 38
https://x.com/sudoingX/status/2109338993620115581
Local AI on your gaming GPUBonsai 2 · opsætning, målinger og kendte faldgruber

Computer use på en rigtig iPhone

iPhone Use kobler Codex til en fysisk iPhone over USB med WebDriverAgent. Reel skærm, taps og scrolling — interessant til de mobilfejl, en desktopbrowser overser. Første opsætning kræver Mac, Xcode og signering.

Promptens rækkefølge koster penge

Oren Melamed viser VS Codes eksperiment med stabile instruktioner først og sessionsdata sidst. I to Opus 5.5-tests faldt de rapporterede credits fra 5,9 til 1,6: et lille arkitekturvalg med mærkbar regning.

Oren Melamed@OrenMe
VS @code is experimenting with something simple that could make sessions significantly cheaper to run: changing the order of the system prompt. Let me explain - A system prompt contains both stable instructions and information that changes between sessions. If that changing information appears too early, it can prevent the model provider from reusing a large portion of the cached prompt. The new experimental setting in @code , chat.copilot.stabilityOrderedPrompt.enabled, addresses this by grouping the system prompt into global, repository, and session-specific blocks. Stable content comes first. Session-specific information moves to the end. The results from two test sessions with Claude Opus 5.5 were interesting: - Cache reads increased from 14.5K to 23K tokens. - Uncached tokens dropped from 10.7K to 2.3K. - Reported credits dropped from 5.9 to 1.6. That's roughly 73% fewer credits for the measured model call!!!! The change is experimental, and it also changes the order in which the model sees instructions, so cost isn't the only thing to validate. The required runtime support is another dependency. The bigger point is that context engineering isn't just about what you put into the context window. It's also about how you structure it - and it is really great to see the team putting the effort to reduce our overall cost of usage One caveat that we need to bare in mind: these are results from a specific test, not a guarantee of the same savings across models, workloads, or sessions.
Billede fra opslaget
♥ 28 · ↻ 3 · 💬 6 · 🔖 16
https://x.com/OrenMe/status/2109352078044983331

Nyhedsbonus

€150 for at få sin README aflivet

Terence Eden betalte rigtige mennesker for at følge sin README og fandt forkerte links, uklare begreber og en rækkefølge, der kun gav mening for forfatteren. Billigere end endnu en perfekt agentreview af ens egne antagelser.

I paid people to try and follow my READMETerence Eden · 11. oktober 2026